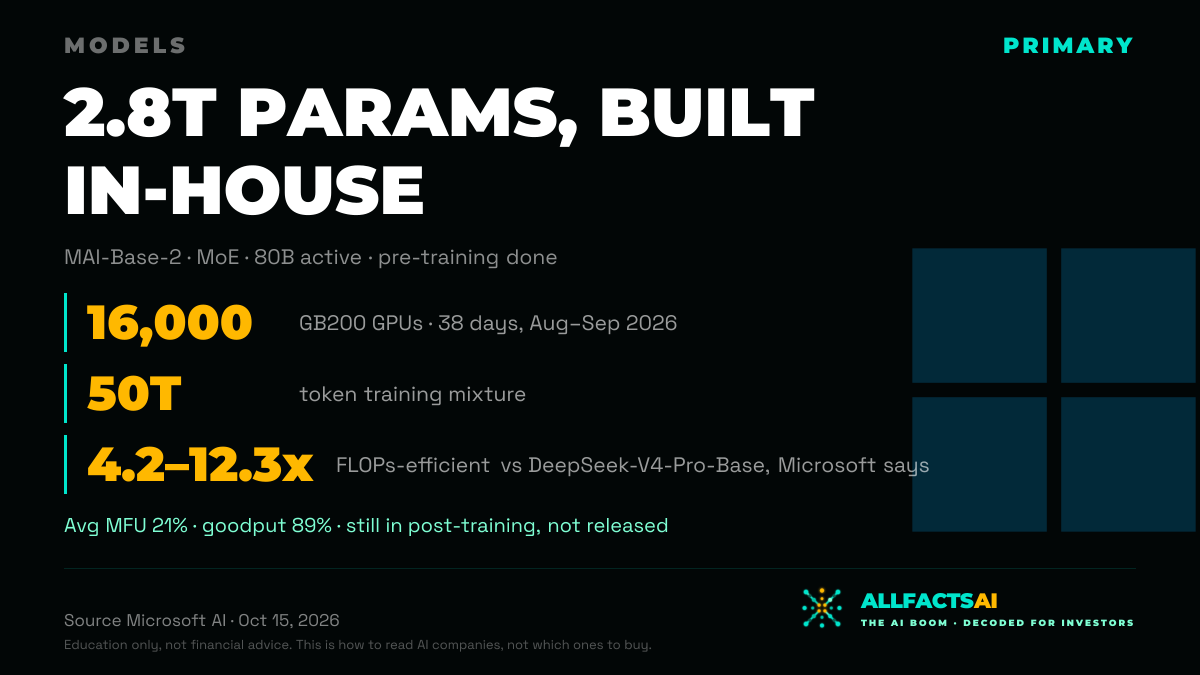
Microsoft AI Finished Pre-Training MAI-Base-2 In-House — a 2.8-Trillion-Parameter MoE Model (80B Active) Trained on 16,000 GB200 GPUs in 38 Days
On Oct 15, 2026, Microsoft AI published "Frontier Pre-training at Microsoft AI", saying it has finished pre-training MAI-Base-2, a mixture-of-experts base model with 2.8 trillion total and 80 billion active parameters. It was trained in-house on 16,000 Nvidia GB200 GPUs over 38 days in August–September 2026 on a 50-trillion-token mixture, at 21% average MFU and 89% goodput. Microsoft says its recipe is 4.2–12.3x more pre-training FLOPs-efficient than DeepSeek-V4-Pro-Base and that the model beats every open-weight model it tested on held-out evals; both are Microsoft's own measurements. The model is still in post-training and has not been released. Business Insider reported Mustafa Suleyman told staff it is stronger than the base model behind GPT-5.6 Sol at a quarter of the compute; that is an unverified internal remark and is not used on the card.